
LightX2V releases a Qwen-Image-2.1 version that needs 4 steps instead of 40
The LightX2V team has published the Qwen-Image-2.1-Lightning-v2-RL model on Hugging Face. It is an accelerated version of the Qwen-Image-2.1 generator that creates and edits images in 4 denoising steps. In the developers' comparison, the base model needs 40. The model has 7 billion parameters and covers three tasks: text-based generation, editing from a single reference, and assembling a frame from several references.
An artist cycling through composition options or running dozens of edits on a single frame gets ten times fewer steps per iteration. This should cut waiting time, although the developers provide no measurements in seconds. There are two important limitations: the model inherited the non-commercial license of the base Qwen-Image-2.1, and the developers themselves warn that in a number of cases the results will have to be checked manually.
What the fast version can do
The model is built on Lightning v2, LightX2V's distilled version of Qwen-Image-2.1. In the new release it was further trained with reinforcement learning using the team's own tool, LightX2V RL. All three modes run at CFG = 1.0, the value set in the release.
- Text to image. An example from the model card: a ceramic teapot next to a bowl of oranges on a wooden table, soft morning light from a window, detailed glaze.
- Editing from a single reference. The model changes the selected detail and preserves the rest. In the developers' example, a character's jacket is recolored dark green, while the prompt requires the face, pose, and surroundings to stay the same.
- Generation from several references. The model assembles a frame from different sources. In the example, the person from the first image puts on the jacket from the second; the prompt requires preserving their appearance and the garment's design and specifies a simple studio background. References must be supplied in the same order in which they are named in the prompt.
The examples in the card are designed for a 1024 × 1024 output. For other aspect ratios, both sides of the frame must be multiples of 32.
What the comparison with 40 steps looks like
LightX2V has published several image pairs from its test runs. In each pair, the original Qwen-Image-2.1 weights at 40 steps are set against the new model at 4 steps. Conditions are identical for both versions: CFG = 1.0, the same full expanded prompts, the same references, and a resolution of 1024 × 1024. The source prompts are open, for example for the scene "Dolphin by a burning shore".
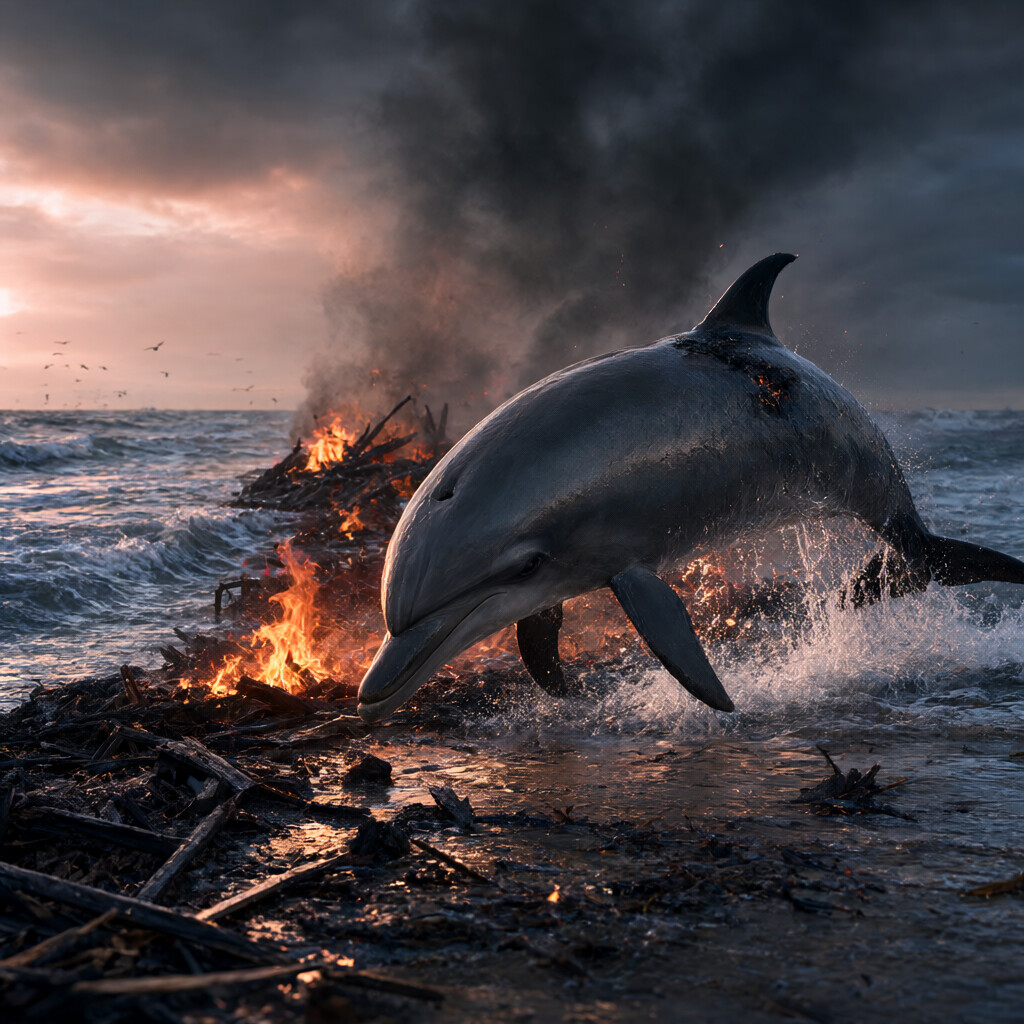
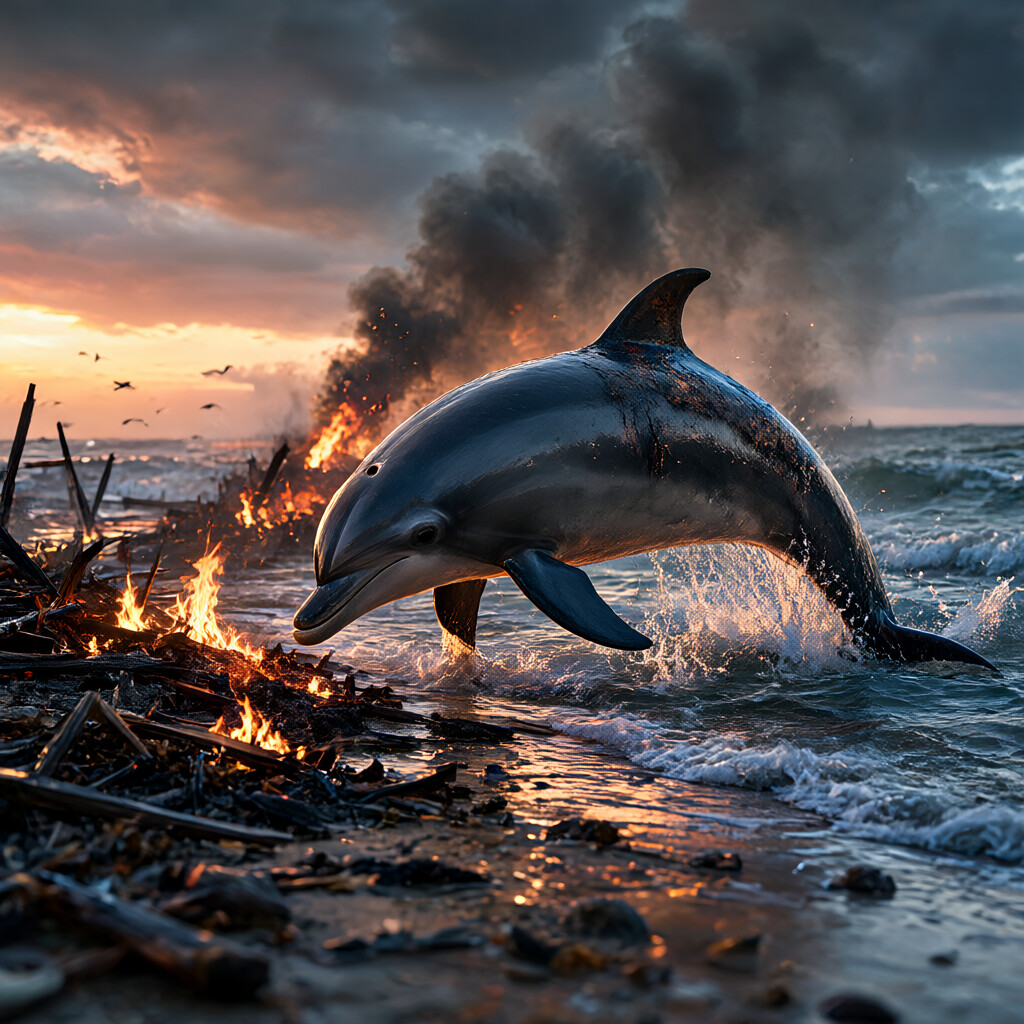
In reference-based editing mode there is, for example, the scene "Flying dragon over gardens with waterfalls": from a single source image, both models build a new frame according to the description.
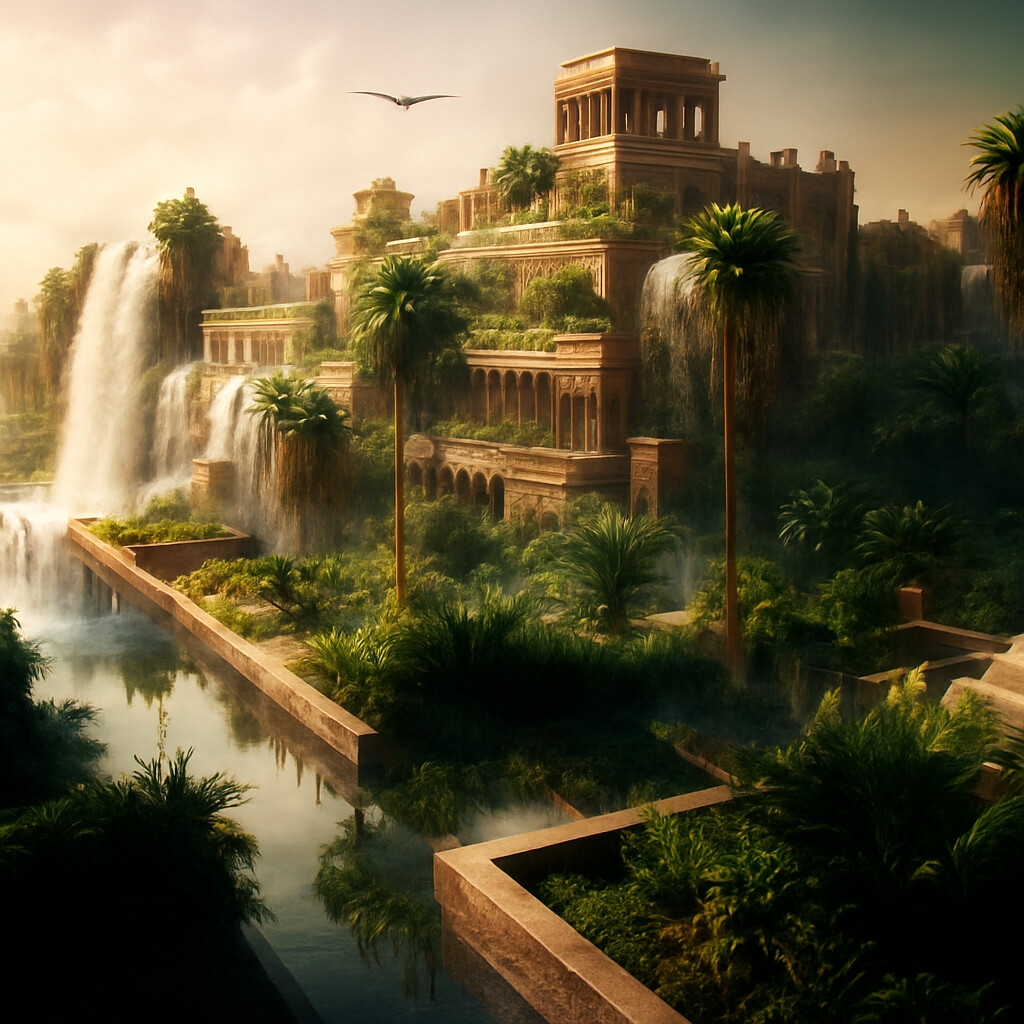
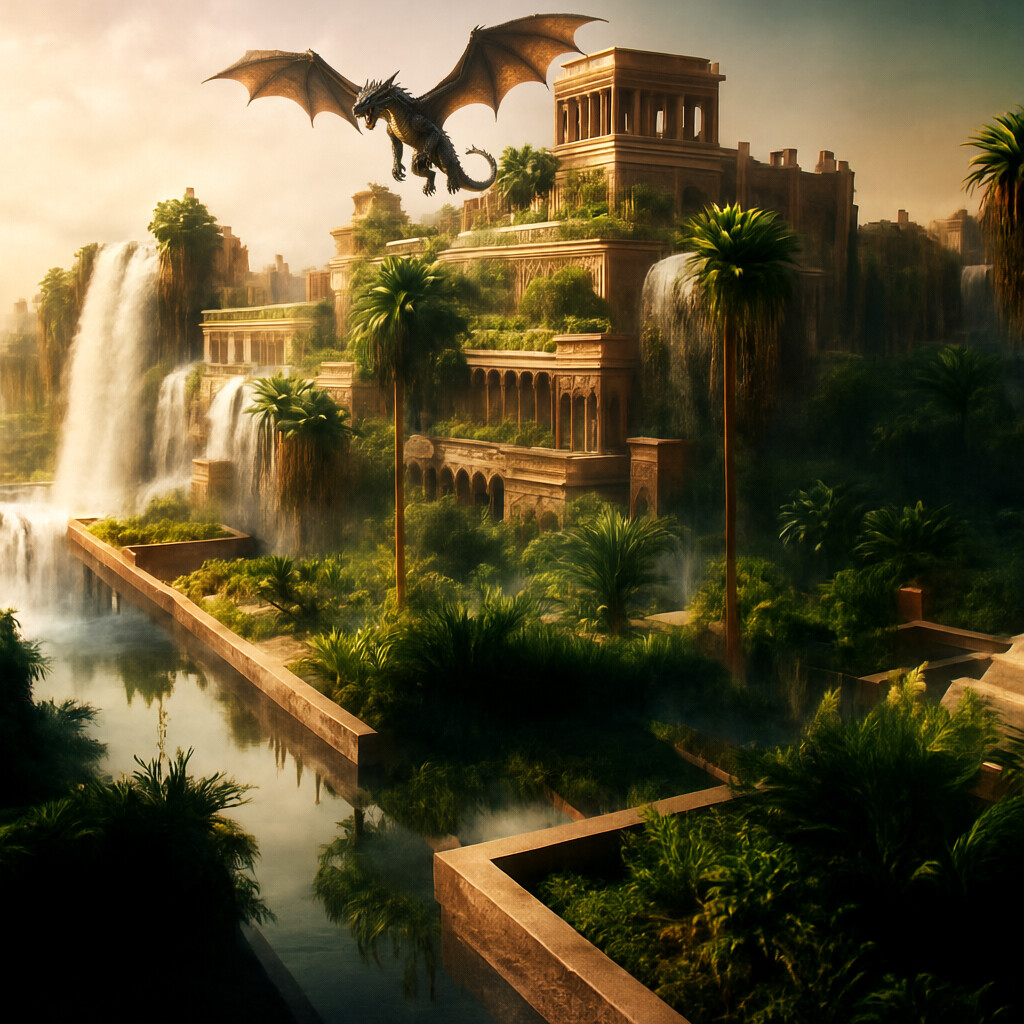
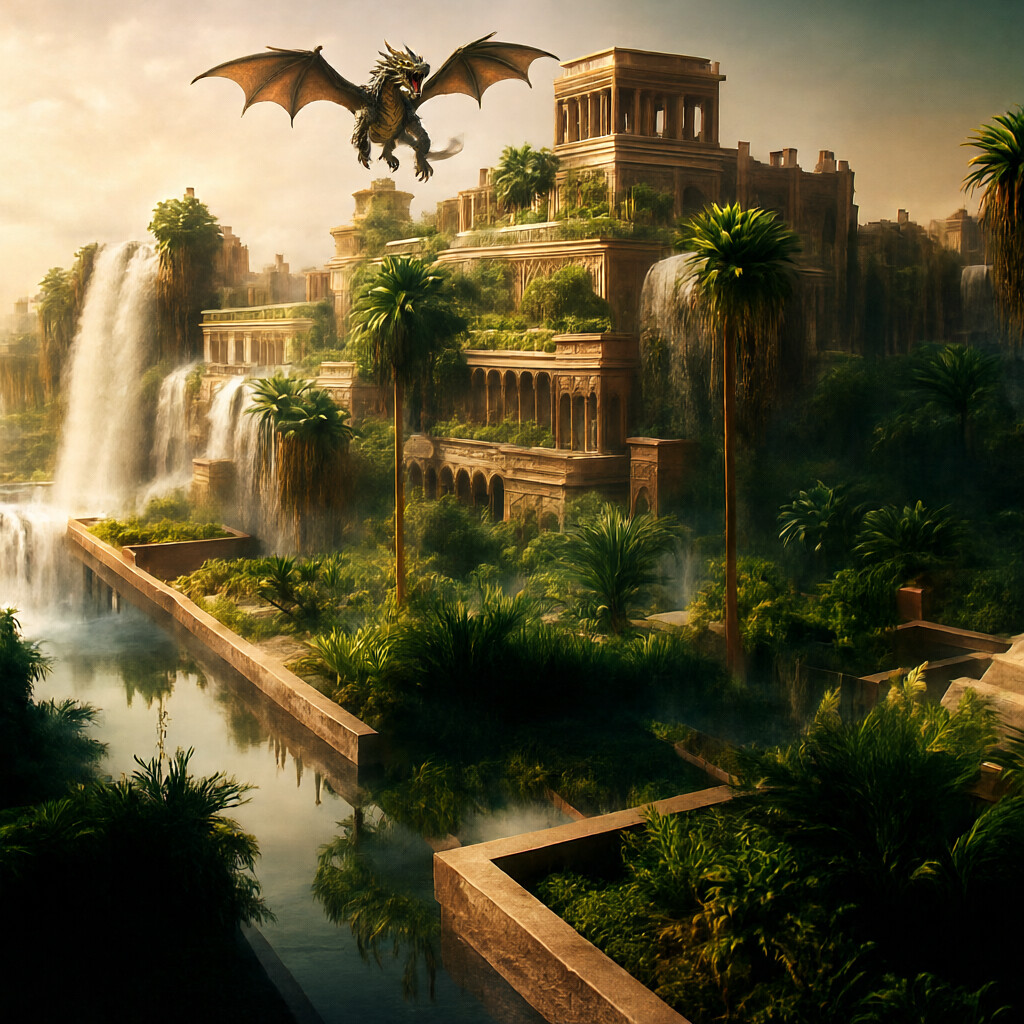
These are selected examples without numerical quality metrics. The developers state outright where the model can go wrong:
"Generation quality may vary depending on the prompt and seed; small text, anatomy, object counts, and exact reference preservation may still require verification."
That is how it is worded in LightX2V's model card. In tasks where precision matters — lettering on packaging, a character's hands, or the recognizability of a specific product — the final image will have to be checked by eye.
What you need to run it
The release is a complete set of weights for the main part of the generator, the transformer, in a single safetensors file. It is not a LoRA adapter, and there is no need to attach it on top of the base model as an add-on. The remaining components (the input data processor, the text encoder, and the VAE) are taken from the original Qwen-Image-2.1 pipeline and downloaded from Hugging Face as needed.
- The weights are stored in FP32, and for operation they can be loaded in BF16.
- You need a recent version of the Diffusers library with Qwen-Image-2.1 support and the transformers library no lower than version 5.17.0.
- Alongside the weights there is a separate file with inference settings: the base model, four noise-level values for the steps, guidance strength, and scheduler parameters. Diffusers does not pick this file up on its own; it is read by the code example from the card.
- The step schedule must be used exactly as specified in the release, and it is the same for all three tasks. Simply setting the number of steps to four does not reproduce that schedule.
The last point concerns everyone who will be embedding the model in their own tools: the schedule will have to be carried over from the release exactly.
License and who will find this useful
The model is derived from Qwen-Image-2.1, so the Qwen Research License applies to it, including its non-commercial terms. The license permits use only for research and evaluation purposes, and commercial use requires a separate license from the rights holder. For a studio or a freelancer, this means the model is suitable for experiments and internal tests, but not for client work.
Over the past month the model has been downloaded 1,449 times, and the base Qwen-Image-2.1 has 88 fine-tuned derivatives on Hugging Face. The new release is part of a five-item LightX2V collection dedicated to Qwen-Image-2.1. As related work, the developers point to their earlier release Qwen-Image-2.1-Lightning and to Qwen-Image-2.1-Turbo from the Qwen team.
What the release does not yet have
The number of steps does not equal generation time: the model card provides no measurements in seconds and no VRAM requirements. Nothing is said about ComfyUI support either, and the official way to run it currently goes through Python code and Diffusers. Until nodes for node-based environments appear, the model will probably go first and foremost to technical artists and pipeline developers who will build it into their tools themselves. For everyone else, it makes sense to wait for integrations before working with it directly.
Without independent comparisons, it is also unclear how the new model stacks up against Qwen's Turbo version and against the first Lightning. The developers show only the comparison with the base model at 40 steps, so choosing between the accelerated variants will have to be done on your own tasks and your own prompts.
Will 4 steps become the new standard for open models, or will the non-commercial license leave LightX2V's distillation a niche toy?